Measurement-efficient Bayesian inference
These are notes for a lecture on choosing measurements with diffusion models. You can also watch the video presentation:
Inverse problems
Problems of the form:
\[y = f(x, n)\]where \(y\) is an observed measurement, \(f\) is a measurement model, \(x\) is the target signal, and \(n\) is measurement noise.
We would like to know \(x\), but \(f\) is not invertible, hence the name ‘inverse problem’.
We like linear inverse problems:
\[y = Hx + n\]where \(H \in \mathbb{R}^{N \times M}\) is not invertible because it has low rank, so we can’t simply compute \(x \approx H^{-1}y\).
Further, because of its low rank, there are typically multiple values of \(x\) that solve \(y = Hx\), i.e. \(H\) is many-to-one. For example:
measured_fish = (mask * fish) + noise

Bayesian inversion
In principle, any value for \(x\) in the masked region solves \(y = Hx + n\). But we want our algorithm to inpaint this region with “plausible” solutions. Bayes’ theorem lets us calculate exactly that:
\[p(x \mid y) = \frac{p(y \mid x)\,p(x)}{p(y)}\] \[\text{with, e.g.:} \quad p(y \mid x) = \mathcal{N}(y; Hx, \sigma_y^2)\]Now sampling \(x \sim p(x \mid y)\) should give plausible solutions, in particular those that have high probability under both the likelihood and the prior.
We can imagine this in terms of ‘slicing’ from the joint space only the region where \(Y = y\), and seeing which values for \(x\) co-occur with that.
Our prior then serves to constrain the image space, making our problem more tractable (less many-to-one).
Measurement-efficient Bayesian inference
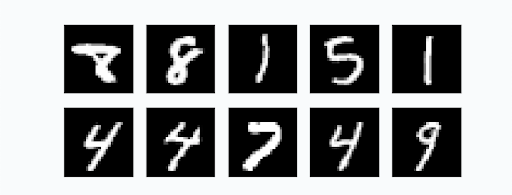
Intuition: MNIST. Where would you sample? Why?
Case study: accelerated MRI. The forward model for MRI is
\[y = U\mathcal{F}(x) + n\]where \(U\) is a subsampling mask and \(\mathcal{F}\) is the Fourier transform.

Imagine we only have 10 minutes to make our scan: which lines should we choose to get the most information about the ‘true’ image?
Another way of asking this question is: which measurements \(y\) would leave us least uncertain about \(x\)?
Fortunately, we can measure this uncertainty using information entropy. In particular, we care about the posterior entropy \(H(x \mid y)\). Our goal then becomes:
\[U^* = \underset{U}{\text{arg min }} H(x \mid y) \quad \text{s.t. } U \text{ contains } K \text{ scan lines.}\]Rather than trying to optimize all lines at once, we can do this iteratively, so that we can use the information we gather along the way to make better decisions. Note that the order doesn’t affect information gain, since the Bayesian updates are commutative.
Along with some other tricks (see the paper), this gives a new objective:
\[\text{scan line}_t^* = \underset{\text{scan line}_t}{\text{arg max }} \left[ H(y_t \mid U_t, y_{0:t-1}) \right]\]The measurements that we expect to be high-entropy are the ones we know least about, and therefore the ones that will give us the most new information.
How can we compute this entropy term? The option we chose:
- Predict \(N\) possible values for \(y_t\) given \(y_{0:t-1}\) (simulation).
- Use the set \(\{y_t^{(i)}\}_{i=0}^{N}\) of simulated possibilities to approximate the distribution as a Gaussian mixture model, \(p(y_t \mid U_t, y_{0:t-1}) \approx \sum_i w_i \mathcal{N}(y_t^{(i)}, \sigma_y^2)\).
- Approximate the entropy of this GMM as a function of the pairwise L2 distances between the simulated \(y_t^{(i)}\) values.
Diffusion models
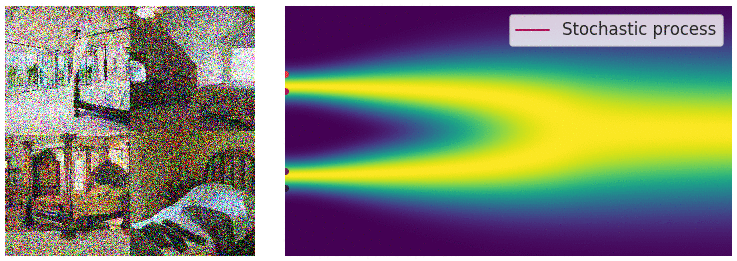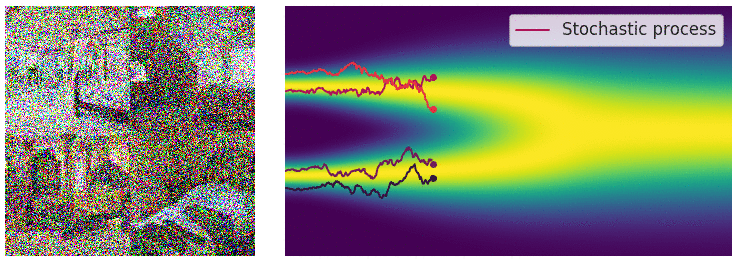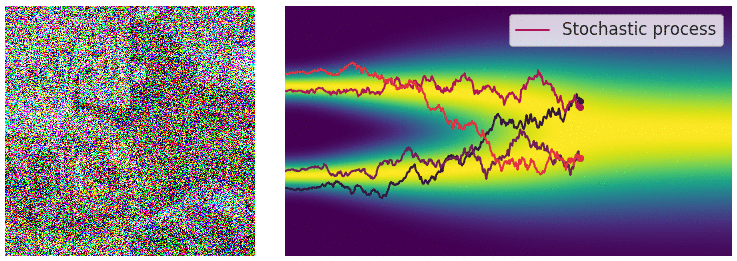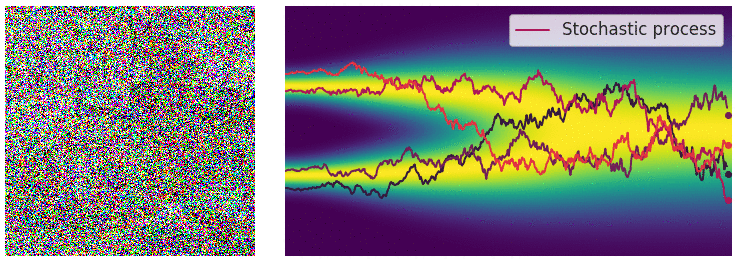 Noising: the forward diffusion process.
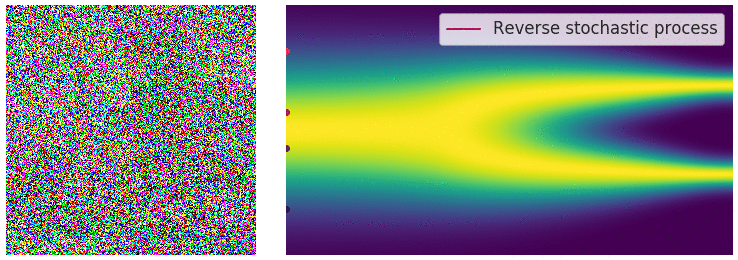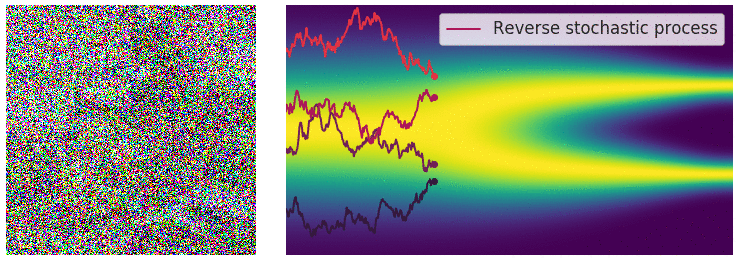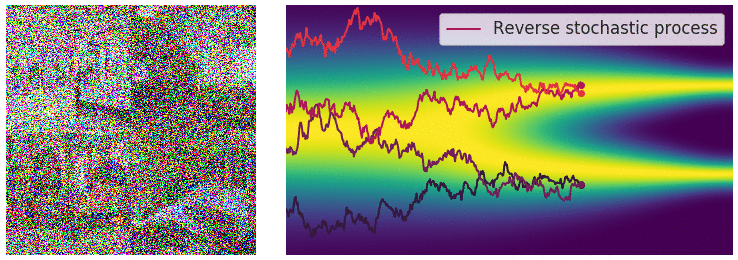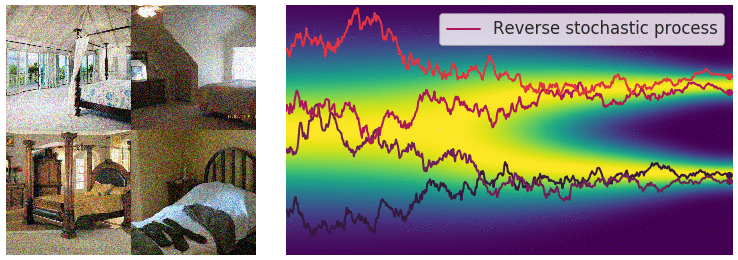 Denoising: the reverse diffusion process. Image credit: Yang Song.
How can we reverse this process?
Training
- Take a clean image \(x_0\) from the training set.
- Randomly choose a time point \(t \sim \mathcal{U}(0, 1)\).
- Add time-dependent noise to make \(x_t\), a ‘partially noised’ version of \(x_0\), and train
where \(\epsilon_0 \sim \mathcal{N}(0, I)\) is the added noise and \(\hat{\epsilon}_\theta\) is a neural network trained to predict the noise \(\epsilon_0\) that was added to \(x_0\) to make \(x_t\).
Inference
- Sample some initial Gaussian noise.
- Repeatedly apply \(\hat{\epsilon}_\theta\) for all \(t\), denoising towards a clean image.
How does this possibly work? There’s another interpretation:
\[\nabla_{x_t} \log p(x_t) = -\frac{1}{\sqrt{1 - \bar{\alpha}_t}}\,\epsilon_0 \approx -\frac{1}{\sqrt{1 - \bar{\alpha}_t}}\,\hat{\epsilon}_\theta(x_t, t)\]Sampling via:
\[x_{t-1} = x_t + c\,\nabla_{x_t} \log p(x_t) + \sqrt{2c}\,\epsilon\] Image credit: Calvin Luo, arXiv:2208.11970.
Posterior sampling with diffusion models
We don’t just want to sample from \(p(x)\) though, we want to sample from \(p(x \mid y)\). In particular, we need to compute the posterior score:
\[\nabla_{x_t} \log p(x_t \mid y) = \nabla_{x_t} \log p(x_t) + \nabla_{x_t} \log p(y \mid x_t)\]We know \(p(y \mid x_0) \propto \lVert y - Hx_0 \rVert^2_2\), but we need \(p(y \mid x_t)\).
Tweedie’s formula
\[\hat{x}_0 := \mathbb{E}[x_0 \mid x_t] = \frac{1}{\sqrt{\bar{\alpha}_t}} \left( x_t + (1 - \bar{\alpha}_t) \nabla_{x_t} \log p(x_t) \right)\]Now we can approximate \(\nabla_{x_t} \log p(y \mid x_t) \approx \nabla_{x_t} \lVert y - H\hat{x}_0 \rVert^2_2\), and we can solve inverse problems using diffusion models!
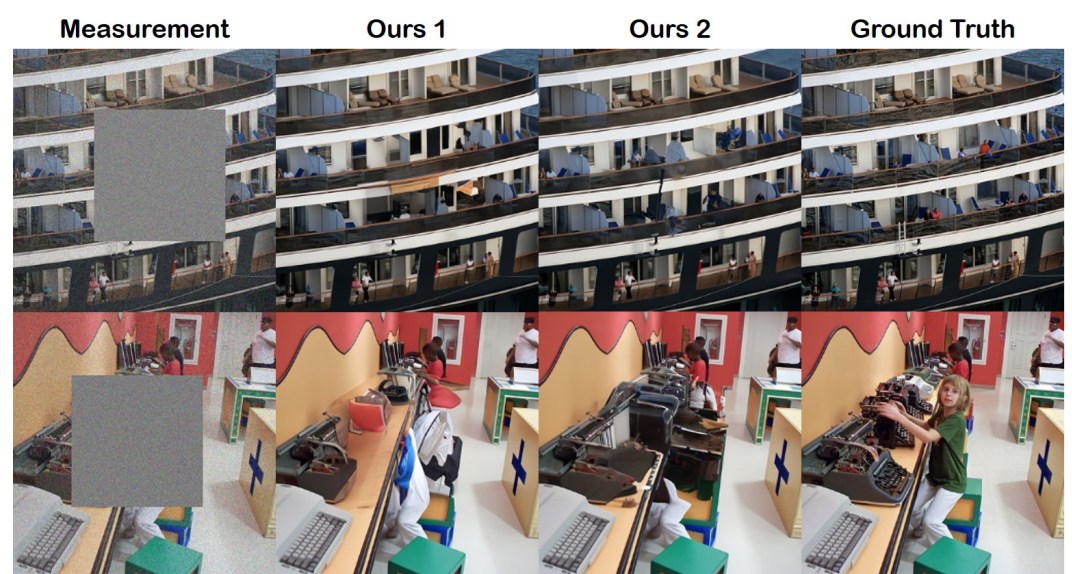 Image credit: Chung et al., arXiv:2209.14687.
Active diffusion subsampling
What if we aren’t given the subsampling mask, but can design it ourselves so as to best solve the inverse problem?
Recall that to find the region with the highest expected information, we’d like to:
- Predict \(N\) possible values for \(y_t\) given \(y_{0:t-1}\) (simulation).
- Use the set \(\{y_t^{(i)}\}_{i=0}^{N}\) of simulated possibilities to approximate the distribution as a Gaussian mixture model, \(p(y_t \mid U_t, y_{0:t-1}) \approx \sum_i w_i \mathcal{N}(y_t^{(i)}, \sigma_y^2)\).
- Approximate the entropy of this GMM as a function of the pairwise L2 distances between the simulated \(y_t^{(i)}\) values.
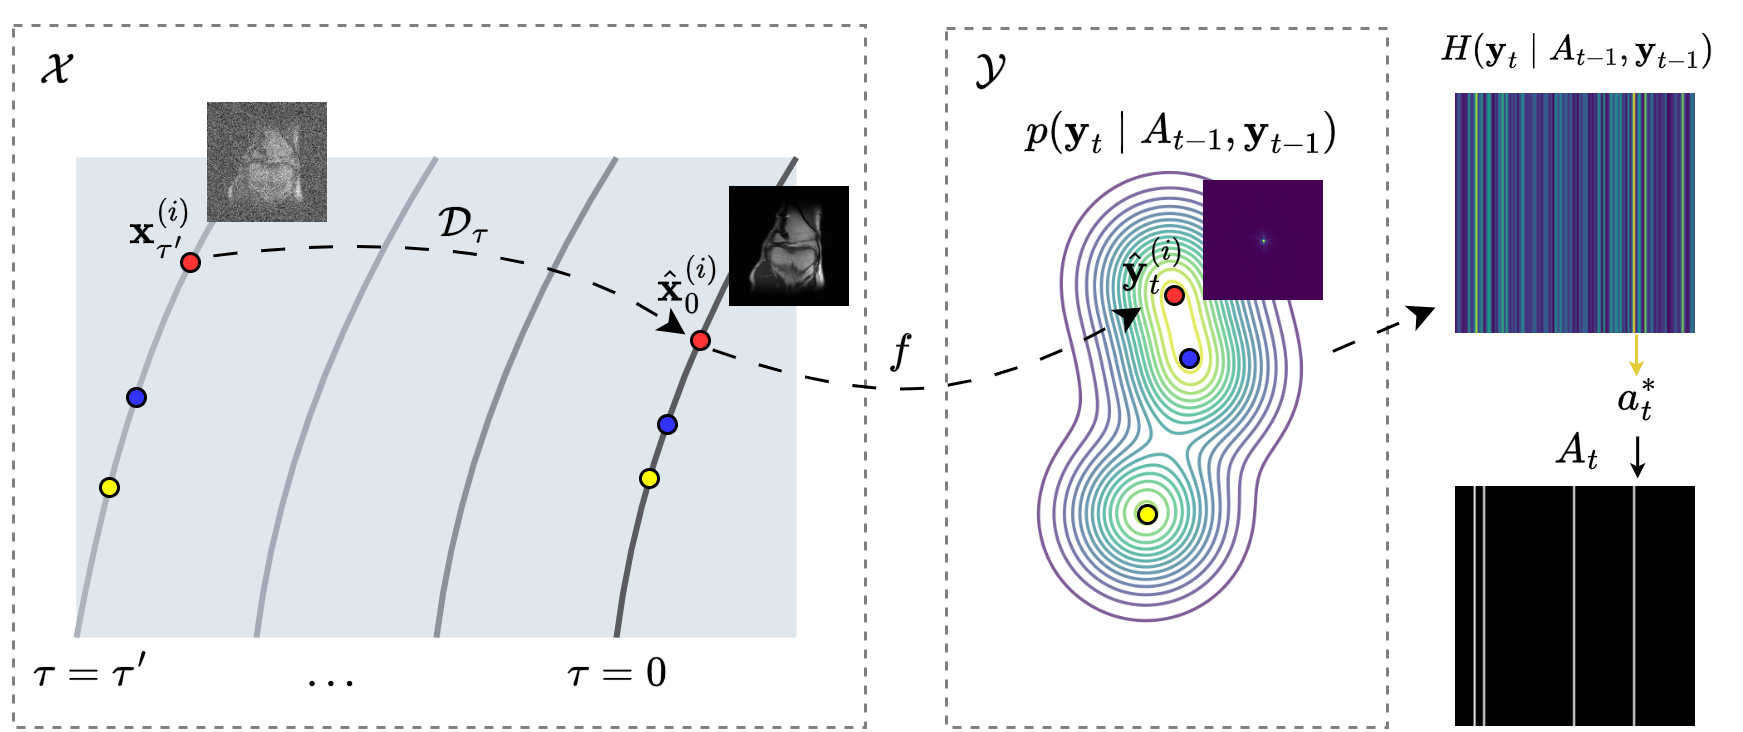
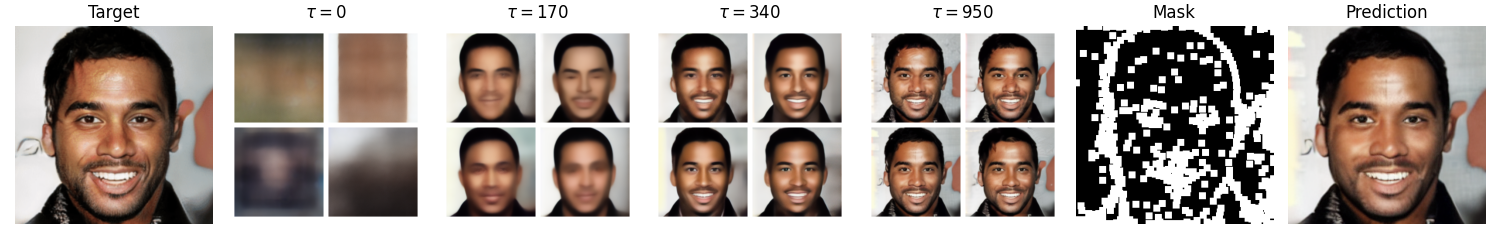
We compute the simulated \(y_t \mid y_{0:t-1}\) values as \(\hat{y}_t = H\hat{x}_0\), using the \(\hat{x}_0\) from Tweedie’s formula that we already compute during posterior sampling. We then run some more denoising steps to ‘ingest’ the newly observed measurement, and repeat!
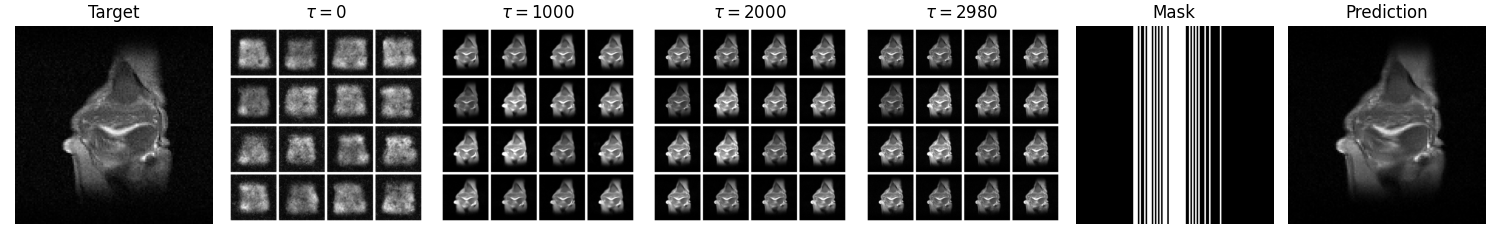
We show that for subsampling, we can easily simulate outcomes for the entire action space (all possible choices of subsampling mask) by learning a diffusion model over fully-sampled images.
We greedily choose which regions of the image to subsample throughout the reverse diffusion process, jointly designing the subsampling mask and reconstructing potential solutions.
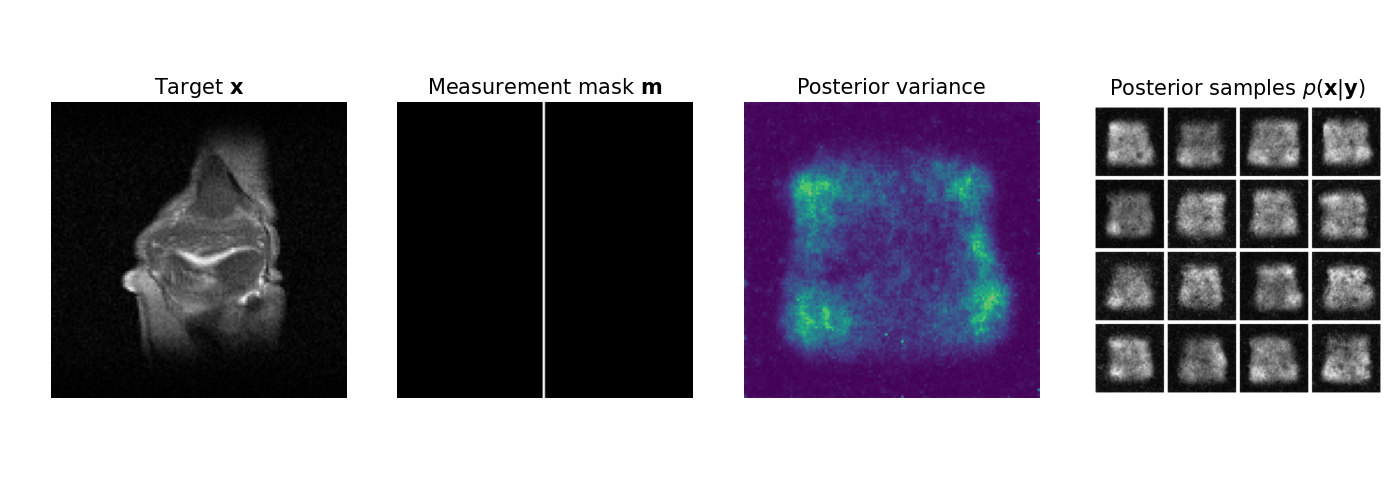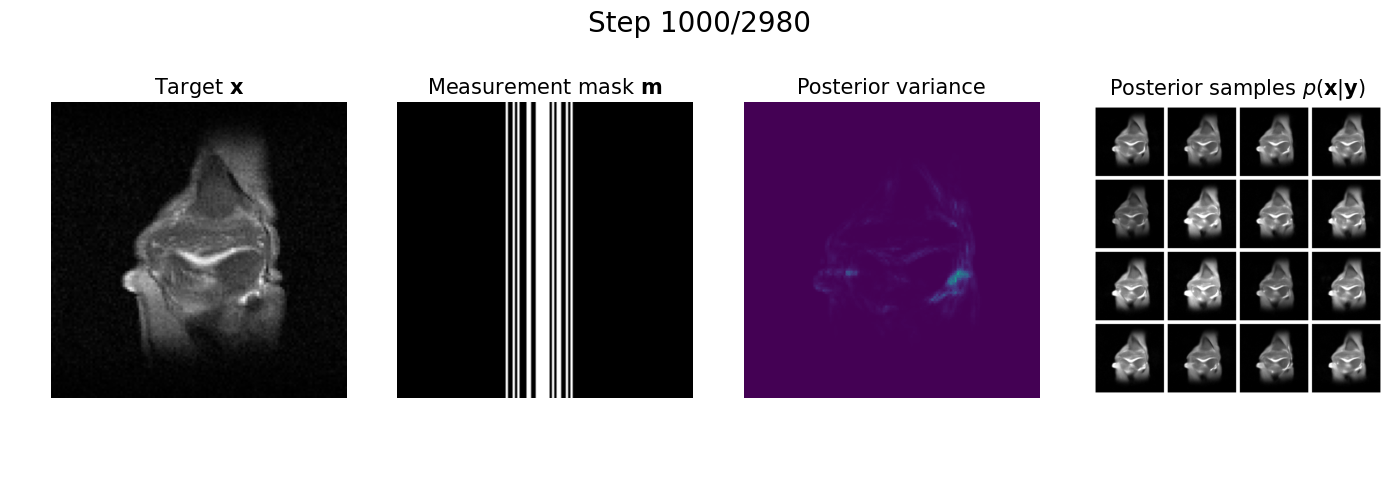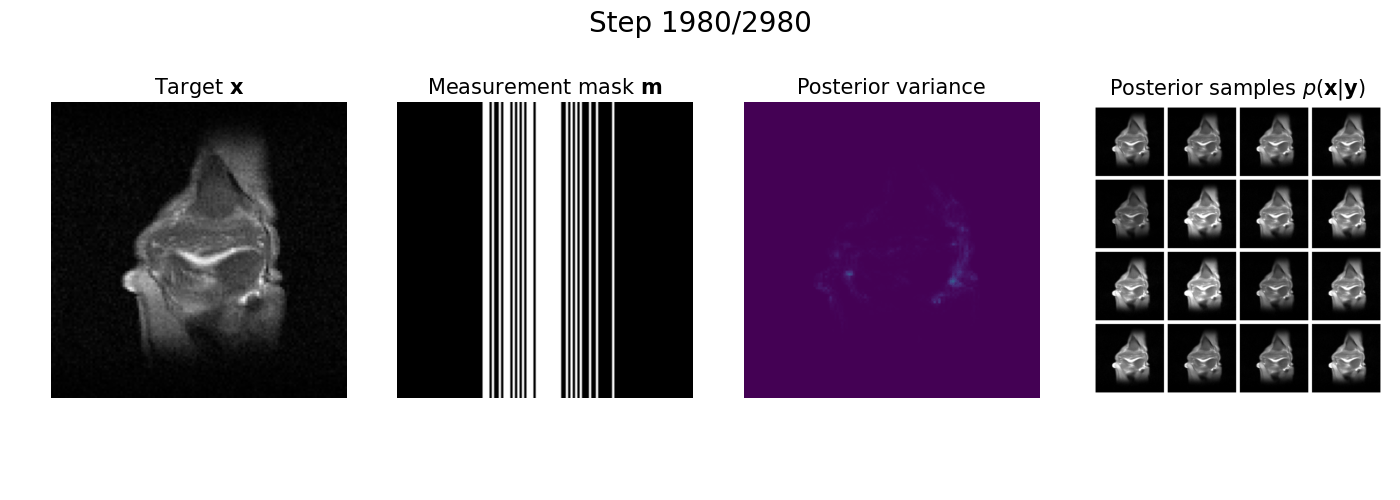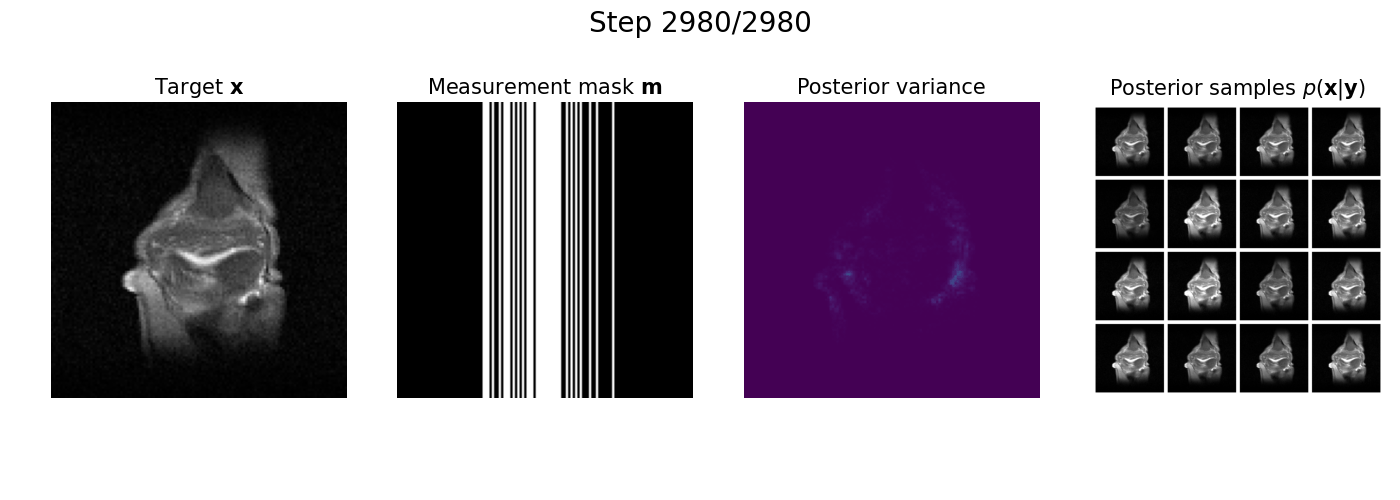
Using Stable Diffusion:
References
- Caticha, A. (2021). Entropy, information, and the updating of probabilities. Entropy, 23(7), 895.
- Luo, C. (2022). Understanding diffusion models: A unified perspective. arXiv preprint arXiv:2208.11970.
- Chung, H., Kim, J., Mccann, M. T., Klasky, M. L., & Ye, J. C. (2022). Diffusion posterior sampling for general noisy inverse problems. arXiv preprint arXiv:2209.14687.
- Nolan, O., Stevens, T. S., van Nierop, W. L., & van Sloun, R. J. (2024). Active Diffusion Subsampling. arXiv preprint arXiv:2406.14388.